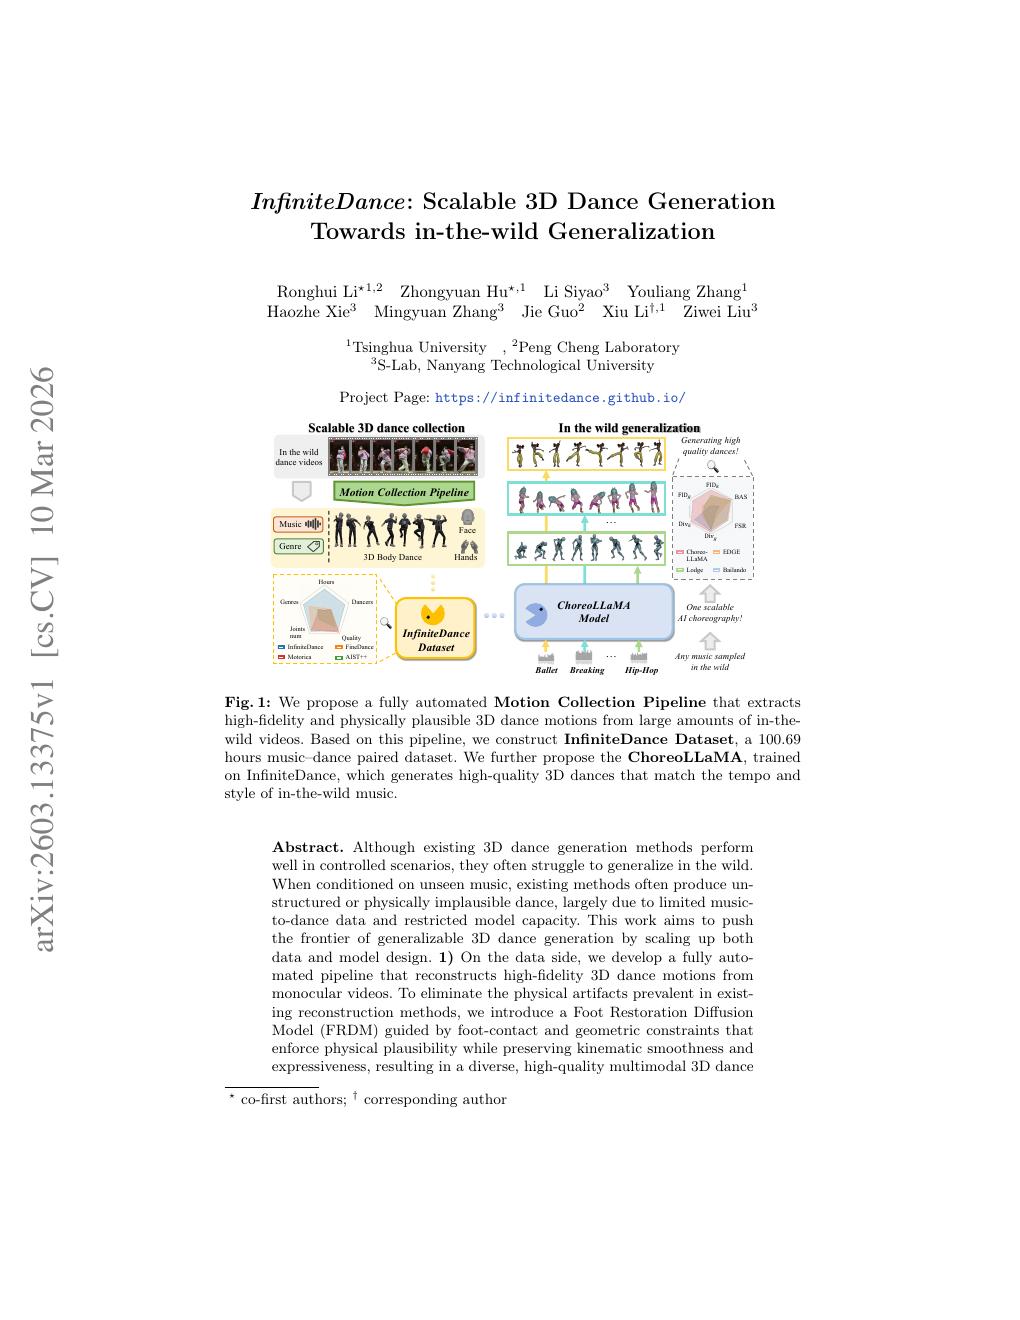
InfiniteDance: Scalable 3D Dance Generation Towards in-the-wild Generalization
ECCV 2026, accepted
Co-first author and core contributor; 100+ hours of multimodal 3D dance data.
I work on generative models for human motion, camera behavior, and dynamic visual content.
I am a first-year Ph.D. student in Control Science and Engineering at Tsinghua University, supervised by Prof. Xiu Li. Before Tsinghua, I received my B.Eng. from Chongqing University, where I ranked first in my class (1/323).
My research focuses on controllable models that connect language, music, human motion, 3D states, camera trajectories, and video.
Previously, I was a Research Intern at Tencent Games, Shenzhen, working on joint human-camera reconstruction.
I am open to research discussions, collaborations, and research internship opportunities.
I study data and model design for dynamic visual worlds, with an emphasis on physically plausible human motion, camera-subject interaction, and controllable generation beyond curated settings.
My recent work spans large-scale 3D dance generation, joint human-camera reconstruction, camera trajectory generation, and controllable video generation.
* denotes co-first authors. My name is underlined.
ECCV 2026, accepted
Co-first author and core contributor; 100+ hours of multimodal 3D dance data.
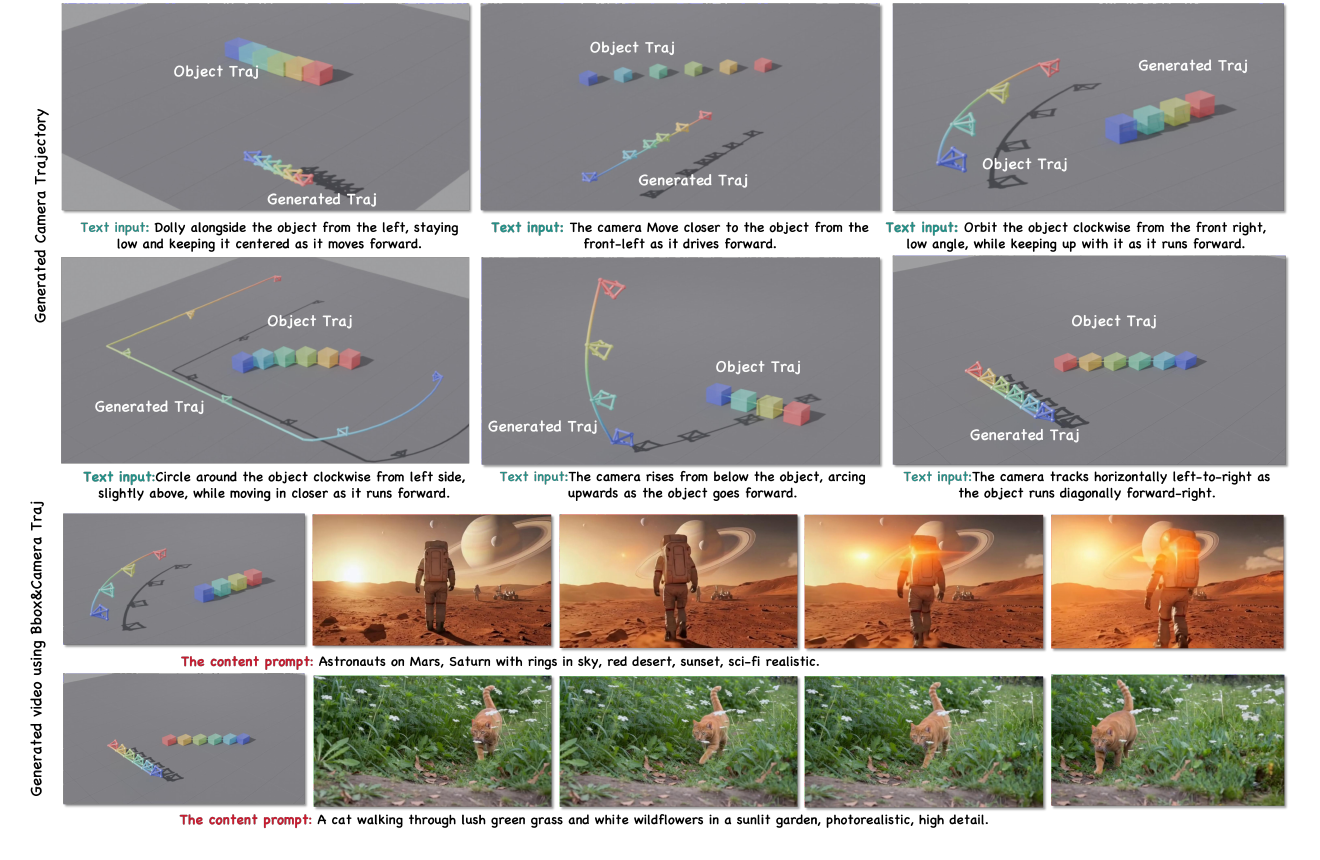
ACM MM 2026, accepted
First author and core contributor; BlockCam benchmark with 41K sequences.
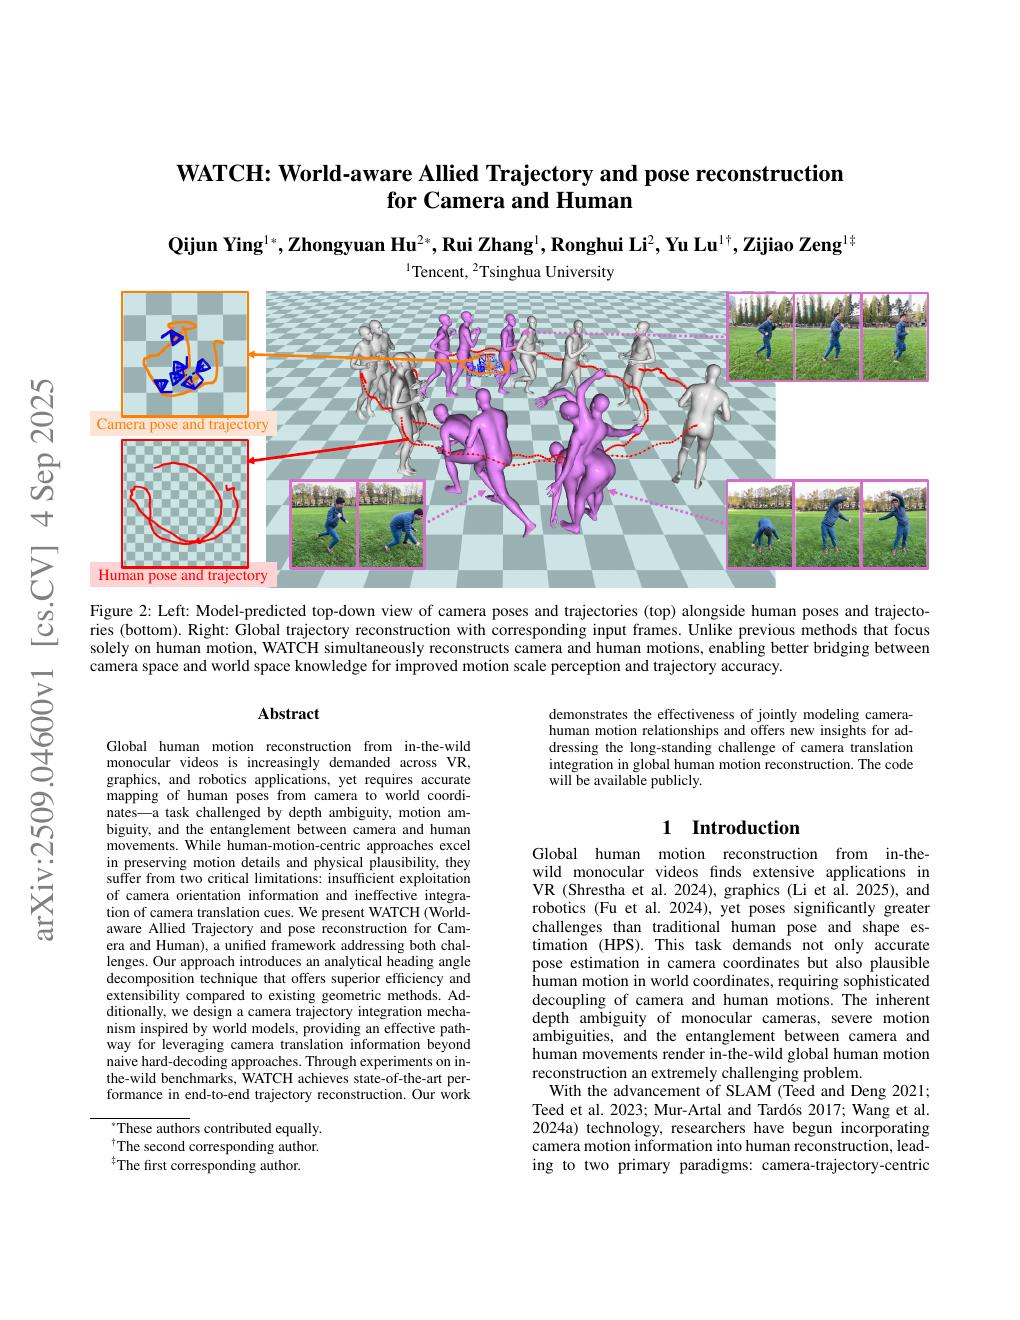
Accepted
Co-first author and core contributor; joint human-camera reconstruction in the wild.
ACM Computing Surveys, under review
Co-first author and core contributor; a taxonomy of controllable video generation.
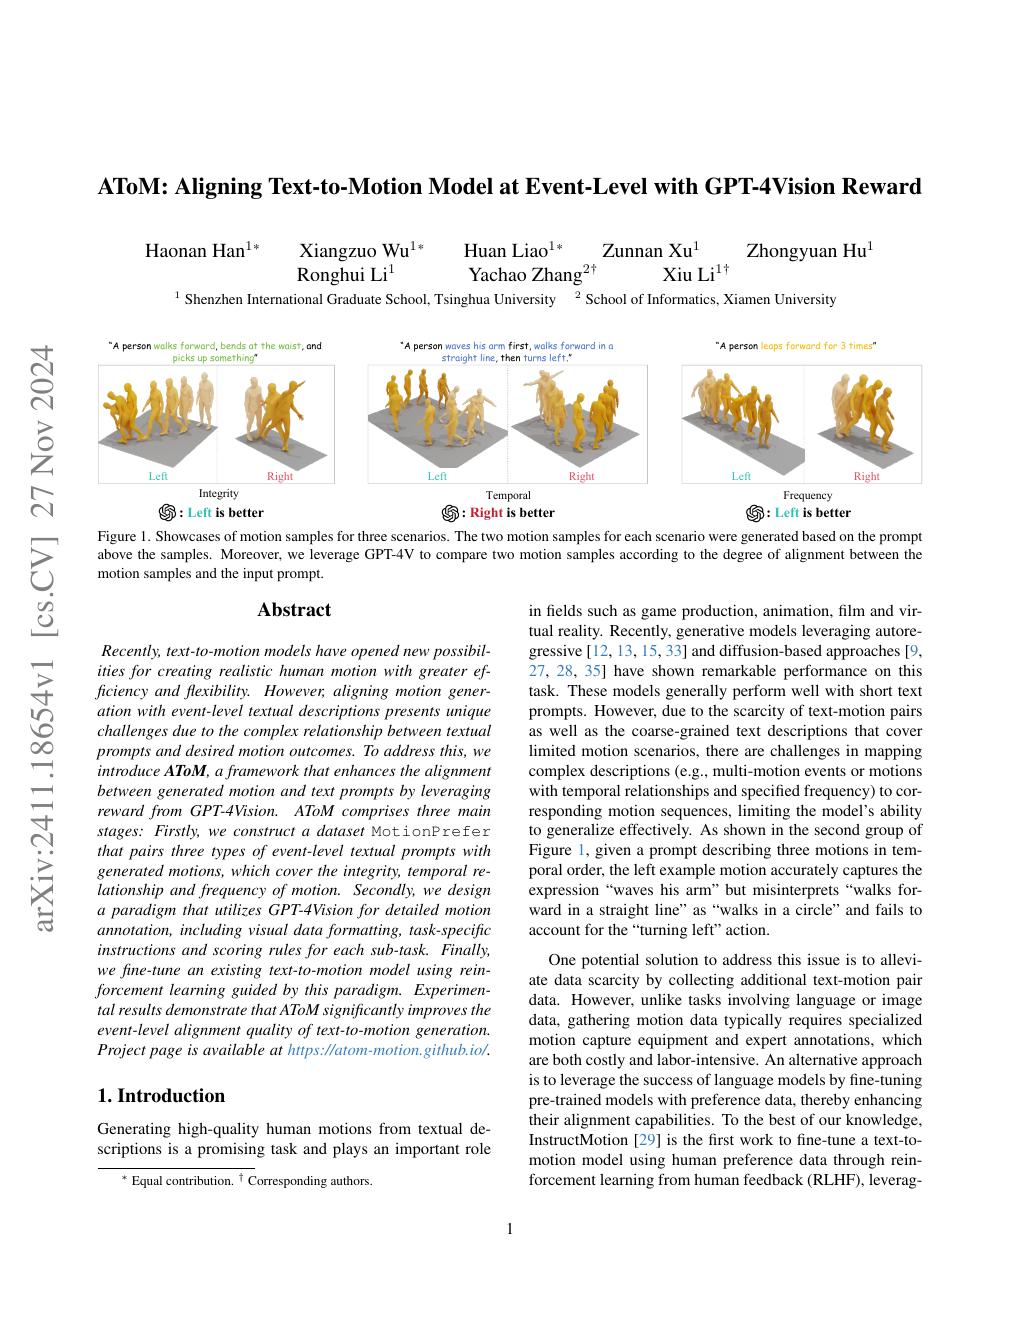
CVPR 2025
Event-level alignment for text-to-motion generation with GPT-4Vision reward.
Ph.D. in Control Science and Engineering, supervised by Prof. Xiu Li.
B.Eng. in Computer Science and Technology. GPA 3.91/4.00; ranked 1/323.
Research Intern, Shenzhen. Human motion capture, pose estimation, and camera estimation.